 JudgeMyAI
Quant-Arena: Benchmarking LLM Agents for Quantitative Trading Research
Quant-Arena benchmarks LLM agents for quantitative trading research, evaluating end-to-end strategy development and execution.
M$^3$R-Bench Reveals Critical Evidence-Mapping Gaps in Multimodal Metaphor Understanding
M$^3$R-Bench exposes critical evidence-mapping failures in multimodal metaphor understanding. Learn how M$^3$R-Reasoner addresses these gaps.
OpenDiscoveryTrace: Enabling Auditable Reasoning for Autonomous AI Scientists
Executive Takeaway OpenDiscoveryTrace delivers the first public, high‑fidelity dataset of 558 complete AI scientific agent trajectories across 124 drug‑discovery, materials‑science, genomics, and literature‑analysis tasks. By recording a nine‑field per‑step trace—thoughts, tool calls, observations, errors, revision triggers, self‑reported confidence, and three auxiliary signals—the dataset makes the *reasoning process* of frontier models (GPT‑5.4, Claude Opus 4.6, Gemini 3.1 Pro) observable, auditable, […]
Layered AI Programming: Architectural, Training, and Safety Implications for Modern LLMs
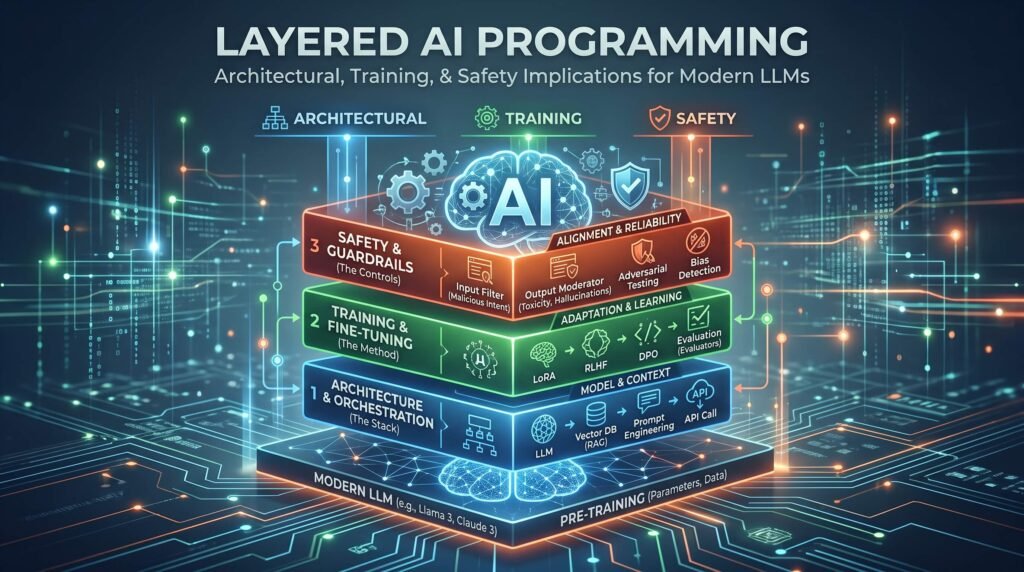
Executive Takeaway The Hacker News (AI Top Stories) announcement proposes a two‑tier architecture for AI‑assisted software development: a core layer that evolves slowly, is manually vetted, and serves as the trusted foundation; and an outer layer that moves rapidly, leverages AI‑generated code, and is continuously repaired by the same models. This separation reshapes every stage […]
Swiss AI Company Surge: Technical Implications of One New AI Firm Every 36 Incorporations
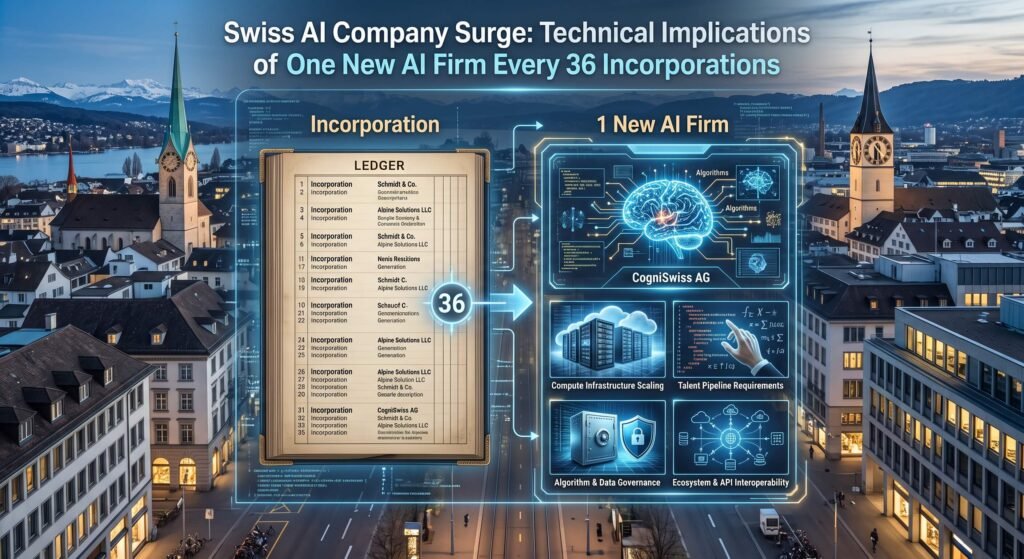
Executive Takeaway Swiss corporate data released on Hacker News (AI Top Stories) announcement shows that, as of Q2 2026, 1 in 36 newly incorporated Swiss companies explicitly claim artificial intelligence in their legal purpose. The AI‑claim share has risen from ~0.3 % pre‑ChatGPT to 2.97 % in the most recent quarter—a 9.1× jump in monthly AI claims after […]